Featured / Performance Guides
Local LLM VRAM Requirements: Sizing 7B to 405B Models
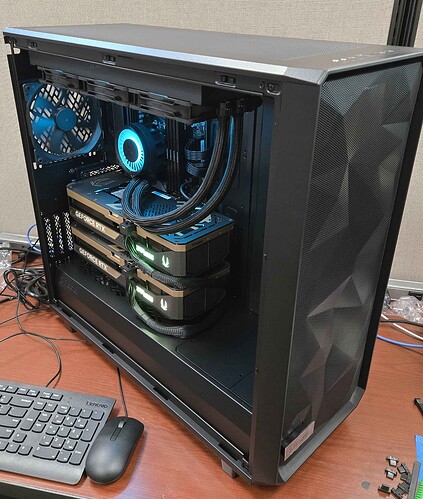
To run a local LLM at full speed, your VRAM has to hold three things at once: the model file, the KV cache for your context, and up to 1 GB of runtime overhead.…